ISTQB Performance Testing Syllabus, Exam Pattern and Study Plan
A checkout page that slows to a crawl on launch day is the kind of failure CT-PT prepares you to prevent. The exam itself is a 90-minute paper of 40 questions on how performance testing is planned, modelled, measured and reported, and you need 26 correct answers (65%) to pass. The syllabus is v1.0 from 2018, the fee is USD $199, and you must already hold the ISTQB Foundation certificate. This guide walks through the syllabus chapter by chapter.
Is syllabus v1.0 from 2018 still the one to study, and what must you hold before booking?
Yes. In October 2026 the ISTQB page for Certified Tester Performance Testing still points to the same document: the Foundation Level Performance Testing syllabus, version 2018, dated 9 December 2018 and listed as v1.0 in its file name. No newer syllabus has replaced it, and the ISTQB sample exam is marked as compatible with it. Study that version and nothing else.
ISTQB states the entry rule on the same page: to gain this certification you must hold the Certified Tester Foundation Level certificate. The syllabus repeats it, saying the Foundation Level core certificate must be obtained before the performance testing exam. If you have not passed CTFL yet, that exam comes first; this one builds on its vocabulary of test levels, test process and risk.
The page also describes who the certification is for: anyone involved in software testing who wants to broaden their knowledge of performance testing, anyone starting a specialist career in it, and people in performance engineering who want a better understanding of how testing fits their work. Candidates sitting the paper in a language that is not their own get 25% extra time, according to ISTQB. Booking runs through the exam providers that ISTQB lists on its certification page.
The exam at a glance
| Item | Detail |
|---|---|
| Certification | ISTQB Certified Tester - Performance Testing (CT-PT) |
| Syllabus version | CT-PT Version 2018 (v1.0) |
| Exam fee | USD $199 |
| Duration | 90 minutes |
| Number of questions | 40 |
| Passing score | 26 / 40 (65%) |
| Prerequisite | ISTQB Certified Tester Foundation Level |
The arithmetic matters for pacing. Ninety minutes for 40 questions leaves 2 minutes 15 seconds a question, and with 40 points on offer you can afford 14 wrong answers. That is generous, but the syllabus is built so that a good share of its objectives ask you to analyse a situation rather than recall a definition, and those take longer to read.
Where do the syllabus's 875 minutes go, and which chapters deserve your evenings?
Each chapter heading in the syllabus carries a minimum training time, and those times are the nearest thing to a weighting that ISTQB publishes. Add them up and the five chapters total 875 minutes, about 14.5 hours of classroom time. The split is lopsided, and your revision should be lopsided in the same way.
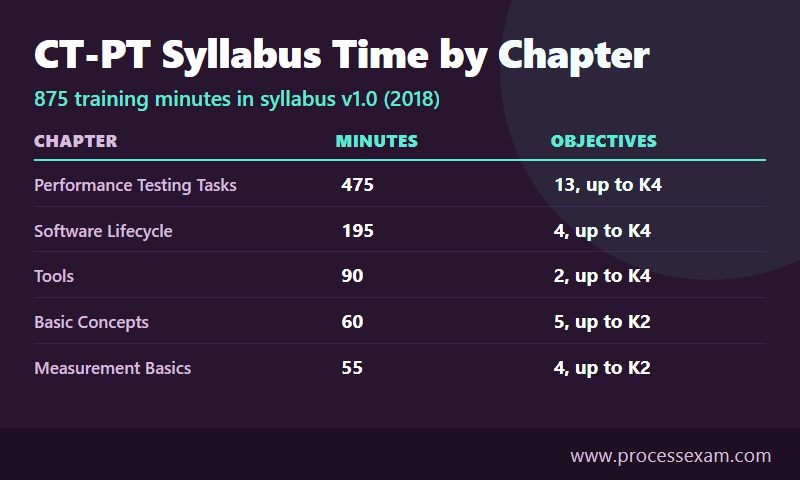
| Chapter | Minutes | Share of 875 | Learning objectives | Highest level |
|---|---|---|---|---|
| 1. Basic Concepts | 60 | about 7% | 5 | K2 |
| 2. Performance Measurement Fundamentals | 55 | about 6% | 4 | K2 |
| 3. Performance Testing in the Software Lifecycle | 195 | about 22% | 4 | K4 |
| 4. Performance Testing Tasks | 475 | about 54% | 13 | K4 |
| 5. Tools | 90 | about 10% | 2 | K4 |
Chapter 4 alone holds more than half the time and 13 of the syllabus's 28 learning objectives. Seven of its objectives sit at K4 (analyse), which means exam questions that hand you a scenario, a table of numbers or a draft plan and ask what follows. Across the whole syllabus there are 2 objectives at K1, 15 at K2, 1 at K3 and 10 at K4. ISTQB adds that everything in the syllabus can be examined at K1, so a definition from the shortest chapter can still appear.
A sensible reading order starts with Chapters 1 and 2, read quickly, because their vocabulary is the language of every later question. Spend the bulk of your hours on Chapter 4, then use Chapter 3 to learn how risk analysis changes from one architecture to another, and finish with the tool-selection factors in Chapter 5, which are short but pitched at K4.
The full list of learning objectives, with chapter numbers, is on our CT-PT syllabus page, and ISTQB publishes the source document as a free PDF.
Which kind of performance test answers which question?
Chapter 1 opens with a quality characteristic rather than a technique. In the ISO 25010 product quality model that the syllabus cites, performance efficiency has three sub-characteristics: time behaviour (how fast the system responds), resource utilisation (what it consumes) and capacity (the limits it can reach). Every test type in the syllabus is a way of probing one or more of them.
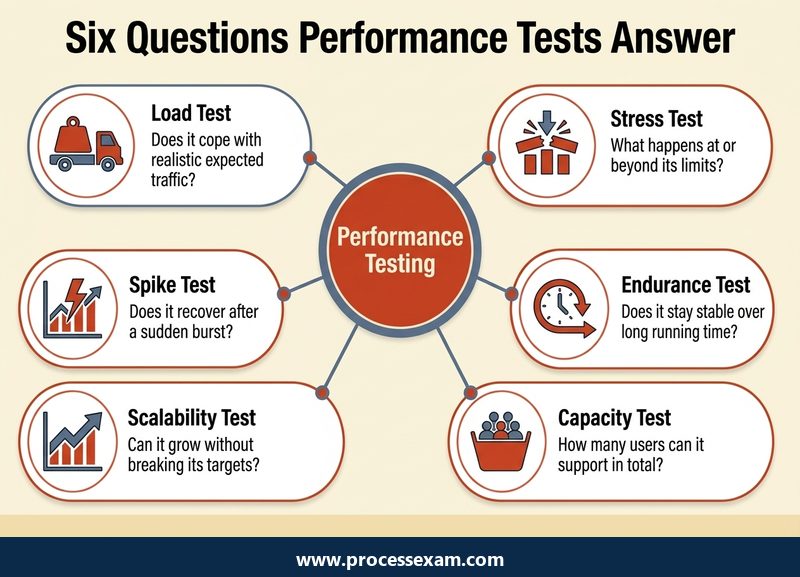
The syllabus defines seven types, and questions often describe a symptom and ask which type would have exposed it.
| Type | What it looks at | A symptom it would expose |
|---|---|---|
| Load testing | Behaviour under increasing, realistic, anticipated load from a controlled number of concurrent users or processes | Pages slow down well within normal traffic |
| Stress testing | Peak loads at or beyond the specified limits, or reduced resources such as bandwidth and memory | The system crashes instead of degrading gracefully |
| Scalability testing | Whether the system can meet future requirements without breaking the current ones | No warning thresholds exist for production monitoring |
| Spike testing | Sudden bursts of peak load and the return to a steady state | A ticket sale opens and the site never recovers |
| Endurance testing | Stability over a period that fits the operational context | Memory leaks, exhausted connections, full thread pools |
| Concurrency testing | Actions that happen simultaneously, such as many users logging in at once | Defects that are very hard to reproduce in production |
| Capacity testing | How many users or transactions the system supports while still meeting its objectives | The data volume a nightly run can handle |
Pay attention to the wording around performance testing itself: it is the umbrella term for any testing focused on responsiveness under load, not a seventh peer of the others. A question that offers "performance testing" as one option beside "load testing" is usually testing that distinction.
Static work counts too
Section 1.3 surprises people who think performance testing means running scripts. The syllabus argues that static testing is often more important here than for functional testing, because so many critical defects are introduced in architecture and design. Reviews of requirements for performance risks, database schemas and queries, system and network architecture, and critical code segments all count. Dynamic testing then starts as early as possible: profiling at unit level, key workflows at component integration, end-to-end behaviour under load at system test, and acceptance testing used to build confidence rather than to hunt defects.
Four ways to generate load
The syllabus lists four options and the trade-off between them is a favourite question style. Generating load through the user interface is representative but impractical beyond small numbers, and a changing interface hurts repeatability. Crowds of real testers can reach very large numbers from varied devices, but the load is less reproducible and harder to organise. Calling the application's API is less sensitive to interface changes and lets one script simulate more users. Replaying captured communication protocols gives repeatable, reliable load at scale, and it is the approach Sections 4.2.6 and 4.2.7 develop.
Four ways a system fails under load
Section 1.5 groups failures by when they appear: slow response at every load level (suspect database design, network latency or background load), slow response only under moderate to heavy load (saturated resources), degradation over time (memory leaks, disk fragmentation, a growing repository), and poor error handling at or beyond the limit (undersized queues, too-short time-outs). Learn each pairing of symptom and typical cause, because the questions run in both directions.
Which measurements does the syllabus expect you to collect, and how do you read them?
Chapter 2 is short, but it supplies the terms the rest of the paper depends on. It begins with a warning: do not run a performance test before you know which metrics you need, because without them requirements cannot be stated in measurable terms, results cannot be compared with a baseline, and judgement drifts into opinion.
Metrics are grouped by the environment they describe. In the technical environment they include response time per transaction or page, resource utilisation (CPU, memory, network bandwidth and latency, disk space, I/O rate, idle and busy threads), throughput of key transactions, batch processing time and the number of errors affecting performance. The business environment adds business process efficiency, throughput of units of work such as orders per hour, service level agreement compliance or violation rates, scope, concurrency and timing of usage. The operational environment covers start-up, backup, shutdown and restoration times and how quickly alerts are raised.
More metrics are not better
The syllabus says plainly that collecting more metrics than required is not a good thing, since each one needs a means of consistent collection and reporting. It offers the Goal-Question-Metric approach as a way to link metrics to goals, while noting that GQM does not always fit, because some metrics describe system health without tying to a goal. Expect an item where one answer proposes "collect everything" and another proposes a defined, obtainable set.
Where the numbers come from
There are three key sources: the performance test tool itself, performance monitoring tools that supplement it and may also watch production, and log analysis tools that mine server logs for high resource usage, memory exhaustion, deadlocks and SQL time-outs. Collecting metrics should disturb the system as little as possible. The syllabus calls any disturbance the probe effect.
Reading results without being fooled
Section 2.4 contrasts functional tests, where a report total is simply right or wrong, with performance tests, which often lack a clear oracle because stakeholders are poor at stating performance requirements. It then warns that raw results mislead. Utilisation can sit under 75% on every likely bottleneck while key transactions run an order of magnitude too slow. Chapter 4 adds the analysis habits behind that warning. Check first that simulated users completed their tasks. Look at minimum, maximum, average and a percentile such as the 90th for response time, remembering that the average can be skewed by outliers and that demanding 100% compliance often costs more than it is worth. Treat failed transactions with suspicion, because a failed transaction takes far less time than a completed one and flatters the transactions-per-second figure.
How do you turn a user count into a load profile without fooling yourself?
Sections 4.2.3 to 4.2.5 are the heart of the K4 material, and they are the part of the syllabus most candidates have never done by hand. The chain runs like this: an operational profile describes how one type of user or component interacts with the system, a load profile combines operational profiles over time, and throughput and concurrency tell you whether the result is realistic.
Operational profiles
To build one you identify personas and roles, the high-level tasks each performs (modelled at business-process or user-story level, not click by click) and the estimated number of each role per unit of time. The data comes from stakeholder interviews and workshops, functional specifications and, where a system already exists, usage data. The syllabus sets out three steps: identify the data, gather it, evaluate it into profiles.
Load profiles
A load profile specifies how many instances of those operational profiles run, and when. The shapes the syllabus names are ramp-ups (steadily more load), ramp-downs, steps (instant changes, such as adding 100 virtual users every five minutes) and distributions that mimic daily or seasonal cycles. Its worked example stacks a steady background of 100 virtual users with a second profile that ramps to 220 and holds for two hours, which together subject the system to three hours of stress. Be ready to read a combined profile like that and say what the system experiences.
Throughput is not the user count
This is the idea the syllabus labours hardest. Concurrent users are an easy number to find and the number most tools ask for, but without an operational profile they say little about load. The syllabus gives the relationship:
System throughput = number of virtual users / (processing time + think time)
Try it with numbers of your own. Take 300 virtual users with a 6-second processing time and 54 seconds of think time: 300 / 60 gives 5 transactions per second. Now let the system slow down so that processing takes 16 seconds. The same 300 users and the same think time give 300 / 70, about 4.3 transactions per second. Nothing about the test design changed, yet the system is receiving 14% less work because it is responding more slowly. That is why a test that holds user count constant can understate the demand a real, open public system would see, where new users keep arriving even while existing ones wait.
The syllabus makes the same point with a different pair of numbers: 500 users each running a short query every minute produce 30,000 queries an hour, while the same 500 users running it once an hour produce 500, a 60-fold difference in load for an identical user count. Concurrency still matters, since each parallel session holds its own resources, and closed systems with a fixed population differ from open ones.
Transactions and think time
A transaction is the set of activities from initiation to completion of one or more processes, and its response time is what you measure. Simulated transactions can include think time to mirror a real user, and the transaction response time plus think time gives the elapsed time. Transactions can be nested, so that an order process is timed as a whole while search, add-to-cart, payment and confirmation are timed separately in the same run.
What goes into a script, a test run and a tool choice?
Chapter 4 continues from analysis into the work of building and running tests, and it asks fewer "name this" questions than "what is missing here" ones.
Protocols and script structure
For performance testing, protocols from the OSI session layer (5) up to the application layer (7) are most commonly used. The syllabus gives database protocols such as ODBC and JDBC, web protocols such as HTTP and HTTPS, and web service protocols such as SOAP and REST as the core examples, and notes that testing embedded, lower-level systems shifts attention to lower layers. A script records or programs the client's requests, then needs parameterisation so that recorded identifiers become variables that change between runs. It typically has an initialisation section, main sections that may repeat, and a clean-up section. Timers wrap each meaningful unit of logical work, and the syllabus reminds you that a protocol-level script measures server and network time while a GUI-level script measures end-to-end time.
Two further points recur. Default error handling in even good tools is minimal, often just an HTTP return code, so the script should add its own checks and, ideally, confirm results indirectly, for example by looking in the database. And a performance script is software, so it deserves quality assurance of its own.
Preparing the environment
Before execution you set up the system under test, deploy the environment, and configure load generation and monitoring. The syllabus is firm that the test environment should be as close to production as possible, and where it is not you must understand the differences and how results will be projected, because performance is a non-linear function of the environment. The most important elements are data, hardware and software configuration, and network configuration; a small or differently structured data set can mislead badly. When part of the system is unavailable, a stub can stand in for it, a practice called service virtualisation, using a third-party credit card service as the example.
Running and reporting
Execution generates load according to the load profile while monitoring every part of the environment. Most tests aim at a steady state, once all users are active, with ramp-up and ramp-down on either side; transient states matter for spike tests or mass log-ins. Reporting then compares data with the objectives, and the recommended actions may change hardware, software or network configuration.
Choosing a tool, and what Chapter 5 does not ask
Chapter 5 is the shortest in the syllabus but carries a K4 objective, so do not skim it. It does not ask you to know the commands of any named product. It describes categories: load generators that create and execute many client instances, a load management console that starts and stops them and aggregates results, and monitoring tools that run beside the system under test, support root-cause analysis and can watch production after release. It also names three licence models: traditional seat or site licences, cloud pay-as-you-go, and open source.
Tool suitability is judged on four factors. Compatibility covers the protocols the system uses, interfaces to external components such as continuous integration, and platforms. Scalability covers the number of virtual users the tool can drive, the load generator hardware it needs and whether load can come from multiple points of presence. Understandability asks what technical knowledge the tool demands, since unskilled testers can configure tests wrongly and produce inaccurate results. Monitoring asks whether the tool's own monitoring is enough or must be supplemented, and whether it can be correlated with defined transactions. Notice that the syllabus says tools are chosen for the organisation, not only one project.
What does Chapter 3 mean by architecture risk, and how do you plan around it?
Chapter 3 is where the K4 objectives are about judgement. Performance risk is not the same for every system, and the syllabus catalogues how it differs. Single computer systems suffer from memory leaks, background software and slow storage. Multi-tier systems add database design, network bottlenecks and per-server capacity. Distributed systems add dependence on remote servers that may be unreliable or intermittently overloaded. Virtualised systems can be starved by other virtual machines on the same hardware or by a badly configured host. Dynamic and cloud-based systems scale on demand, so the risk is a self-scaling feature that was configured wrongly or never updated. Client-server systems add connection speed, congestion at the client end and the effect of firewalls and load balancing, mobile applications add limited and variable device resources, and embedded real-time systems add the risk of running out of memory or missing an update rate.
A repeatable risk process
The syllabus's process has four steps: identify risks to time behaviour, resource utilisation and capacity; assess them for likelihood and impact with defined criteria, making sure the relevant architecture categories are covered; mitigate according to the nature and level of risk; and manage risks continuously until release. It wants both business and technical stakeholders in the room, and it wants the analysis to start early and repeat. Waiting for system test is the failure it warns against, since many large projects have met late surprises from decisions made early. Its example is a poorly designed many-to-many database join that only shows up with large data sets at system test, but which an experienced database engineer could have predicted in a design review.
Plans and objectives
Chapter 4 begins with objectives. The syllabus separates user-based objectives, about satisfaction and business goals, from technical objectives, about scale and the conditions under which performance degrades. It also gives the questions to ask stakeholders: which transactions will run and what average response time is expected, which system metrics should be captured and what values are expected, and what improvement is expected against earlier cycles. The performance test plan then records objectives, a system overview, test types, acceptance criteria tied to objectives, service level agreements and baselines, test data, system configuration, environment, and tools, among other items. One line is worth memorising: response time is generally a user concern, throughput a business concern and resource utilisation a system concern.
Chapter 4 also asks you to create a presentation that lets stakeholders understand results, which is why a sound answer to a reporting question usually matches the message to the audience instead of listing every metric.
How do you rehearse the paper, and where does this certificate fit afterwards?
Use your last study block for rehearsal rather than more reading. ISTQB publishes Sample Exam A, compatible with the 2018 syllabus, with a separate answers file on the same site. Work through it against a 90-minute clock, then read the rationale for every item you missed or guessed and trace each one back to a chapter and an objective. If the same K4 chapter keeps costing you answers, return to its worked examples (throughput, load profiles, percentiles) and redo the arithmetic by hand.
When one set is not enough, a larger bank of timed papers lets you check that a good score is not just memory of items you have already seen. Our CT-PT mock exam adds extra timed sets in the same 40-question, 90-minute shape, so a sample-exam score that might be luck can be tested again. Whichever material you use, aim to finish with ten spare minutes and a score comfortably above 26.
What comes next
The ISTQB page lists nine business outcomes for a passing candidate, from understanding performance efficiency and defining risks, goals and requirements, to analysing results for stakeholders and aligning performance testing with the software lifecycle. In practice the certificate signals that you can talk to developers, architects and operations staff in a shared vocabulary and plan a performance test sensibly. The syllabus itself says the performance material in the Advanced Level Technical Test Analyst syllabus is consistent with this one and developed by it, which makes CT-PT a natural complement for testers who later work toward that certification. It does not make you a performance engineer; the tooling skill comes from projects.
Because the syllabus names no tools, there is nothing to relearn when a tool vendor ships a new release. The vocabulary and reasoning you build here transfer to any load tool you meet.
Frequently Asked Questions
How many questions are in the CT-PT exam and what is the pass mark?
The CT-PT exam has 40 questions in 90 minutes, worth 40 points in total. You need 26 points to pass, which is 65%. ISTQB gives candidates taking the exam in a language that is not their native one an extra 25% of time.
Is the CT-PT syllabus v1.0 from 2018 still current?
Yes. Checked on the ISTQB CT-PT page in October 2026, the syllabus offered is version 2018, listed as v1.0 and dated 9 December 2018. ISTQB's Sample Exam A is marked as compatible with that version, so study from it and not from older summaries.
Do I need the Foundation Level certificate before taking CT-PT?
Yes. ISTQB states that to gain the Performance Testing certification, candidates must hold the Certified Tester Foundation Level certificate. The syllabus repeats this entry requirement, so pass CTFL first and then book the specialist paper.
Which CT-PT chapter should I spend the most time on?
Chapter 4, Performance Testing Tasks. It is recommended at 475 of the syllabus's 875 training minutes and holds 13 of its 28 learning objectives, seven of them at K4. Planning, load profiles, throughput arithmetic, scripts and results analysis all sit there.
Does CT-PT test knowledge of a specific load testing tool?
No. Chapter 5 covers categories of tool, such as load generators, load management consoles and monitoring tools, and the factors for choosing one: compatibility, scalability, understandability and monitoring. The syllabus does not ask for commands or scripts in any named product.
- Specialist |
- ISTQB Performance Testing Test Questions |
- CT-PT Question Bank |
- ISTQB Performance Testing Book |
- Performance Testing Certification Cost |
- Performance Testing Certification Requirements |
- ISTQB Performance Testing Sample Questions |
- CT-PT Exam Questions Download |
- CT-PT Test Questions |
- Performance Testing PDF |
- CT - Performance Testing Mock Exam |
- CT - Performance Testing Simulator |
- CT - Performance Testing Certification |
- CT - Performance Testing Certification Cost |
- CT - Performance Testing Certification Requirements |
- ISTQB CT - Performance Testing Book |
- ISTQB CT - Performance Testing Question Bank |
- ISTQB CT - Performance Testing Study Guide |
- CT - Performance Testing |
- CT - Performance Testing PDF |
- ISTQB CT - Performance Testing Exam Questions |
- ISTQB CT - Performance Testing Sample Questions


