ISTQB CT-GenAI Syllabus v1.1: What the Exam Rewards
Updated on 23 September 2026. What’s new: the pass mark is 30 of 46 points, ISTQB Foundation Level is a required entry condition, and the syllabus in force is v1.1 of 27 April 2026
ISTQB runs the CT-GenAI exam on syllabus v1.1, dated 27 April 2026. The paper is 40 multiple-choice questions in 60 minutes, marked out of 46 points, and 30 of those points pass you. What that scoring hides is how uneven the module is: one chapter of the five, prompt engineering, is worth 16 points on its own. Study time spread evenly across the syllabus is study time spent badly.
This article works through the module the way the exam is actually built: the version in force, the entry condition, the shape of the paper, the point weight of each chapter, and then the two chapters that decide most results. Every figure below comes from one of three places, and each one is named where it appears -- the ISTQB certification page for CT-GenAI, the ISTQB Exam Structures and Rules tables, and the CT-GenAI syllabus itself. Figures were checked in September 2026.
Which syllabus version does the CT-GenAI exam run on right now?
Version 1.1, released on 27 April 2026. The module first appeared as v1.0 on 25 July 2025, so the certification is barely a year old, and v1.1 is recorded in the syllabus revision history as a minor update rather than a rewrite. The chapter structure survived it: five examinable chapters, the same names, the same recommended teaching minutes. What changed is wording and detail inside the sections, which matters if you are studying from a copy you downloaded last year.
The credential itself has not been renamed. ISTQB lists it as a Specialist Level module, Certified Tester Testing with Generative AI, code CT-GenAI, on its certification page for the module. If you have seen the phrase "Certified Tester Specialist Level" on the syllabus cover and wondered whether you were looking at a different qualification, you were not -- Specialist is the stream, CT-GenAI is the module.
One confusion is worth clearing before anything else, because it sends candidates to the wrong syllabus entirely. CT-GenAI is about testing with generative AI: using large language models to help you analyse, design, generate and monitor testing. It is not the module about testing AI-based systems as the object under test. That is a separate ISTQB specialist module with its own syllabus and its own exam. If your job is to find defects in a machine-learning product, CT-GenAI is not the paper you want.
A practical consequence of the version churn: download the syllabus again before you start revising, and check the date on the cover page. A v1.1 cover reads 27/04/2026. Anything older is a v1.0 copy, and while the skeleton is the same, quoting a superseded definition back at a scenario question is an avoidable way to lose a point.
Do you need Foundation Level before you can book CT-GenAI?
Yes. This is the single most misreported fact about the module. ISTQB states the condition in two places, and both are unambiguous. The certification page carries the line that you must be certified ISTQB Certified Tester Foundation Level before taking the CT-GenAI exam, and section 0.6 of the syllabus repeats it: the Foundation Level certificate shall be obtained before sitting this exam. It is an entry requirement, not a recommendation, and it is not something a local board waives on request.
That has a scheduling consequence people underestimate. If you do not already hold Foundation Level, your CT-GenAI plan is really two exam plans stacked, and the Foundation paper has to clear first. Budget for that rather than discovering it at the booking screen.
Beyond the certificate, ISTQB describes the audience broadly. The syllabus names testers, test analysts, test automation engineers, test managers, user acceptance testers and developers as the core readership, and then adds project managers, quality managers, business analysts, IT directors and management consultants as people who want a working understanding rather than a daily toolset. There is no stated requirement for years of experience and no coding prerequisite. You will meet architecture terms in chapter 4 -- retrieval-augmented generation, vector databases, fine-tuning, agents -- but every learning objective attached to them asks you to explain or summarise, never to build.
What does the exam paper look like on the day?
Small, fast and scored on points rather than on questions, which is where most of the confusion about the pass mark comes from. Here is what the figures say for this module.
| Item | CT-GenAI |
|---|---|
| Full name | ISTQB Certified Tester - Testing with Generative AI |
| Exam code | CT-GenAI |
| Category | Specialist |
| Syllabus version | Version 1.1, dated 27 April 2026 |
| Questions | 40 multiple choice |
| Total points | 46 |
| Passing score | 30 / 46 (65%) |
| Duration | 60 minutes |
| Extra time | 75 minutes where the exam is not in your native language |
| Exam fee | USD $199 |
| Entry condition | ISTQB Foundation Level certificate |
| Delivery | Pearson VUE |
Forty questions carry 46 points because not every question is worth one point. The ISTQB Exam Structures and Rules tables set out the rule for each module: CT-GenAI questions written at K1 and K2 are worth one point each, and the six questions written at K3 are worth two. That is where the extra six points come from. The pass mark of 30 is simply 65% of 46, rounded up from 29.9.
The same tables give the cognitive mix, and it is worth knowing before you decide how to revise. Eight questions are K1, which is recall. Twenty-six are K2, which is understanding -- explain, distinguish, summarise, compare. Six are K3, which is application: you are given a situation and asked what you would do. ISTQB budgets one minute for each K1 and K2 question and three minutes for each K3 question, which totals 52 minutes of the 60. Eight minutes of slack across a whole paper is not much, and it is the reason candidates who over-read the early recall questions run out of road on the applied ones.
Where English is not your first language and the exam is delivered in English, the published allowance is 25% more time, taking the 60 minutes to 75. That sits on the ISTQB certification page alongside the format, and it is worth claiming at booking rather than discovering afterwards that you could have had it.
Where does the marking weight actually sit across the five chapters?
Unevenly, and knowing how unevenly is the cheapest advantage available to you. The Exam Structures and Rules tables publish a per-chapter breakdown for every ISTQB module, and for CT-GenAI it reads like this.
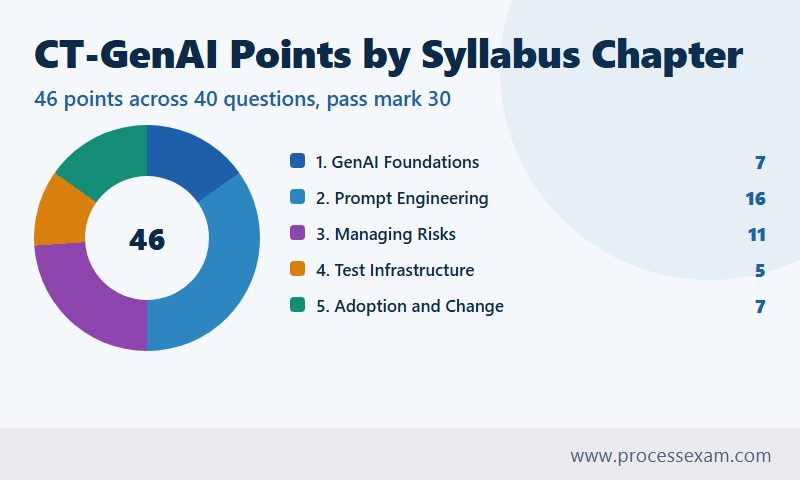
| Chapter | Questions | Points | Teaching minutes |
|---|---|---|---|
| 1. Introduction to Generative AI for Software Testing | 7 | 7 | 100 |
| 2. Prompt Engineering for Effective Software Testing | 11 | 16 | 365 |
| 3. Managing Risks of Generative AI in Software Testing | 10 | 11 | 160 |
| 4. LLM-Powered Test Infrastructure for Software Testing | 5 | 5 | 110 |
| 5. Deploying and Integrating Generative AI in Test Organizations | 7 | 7 | 80 |
| Total | 40 | 46 | 815 |
Read the points column, not the questions column. Chapter 2 holds 11 of the 40 questions but 16 of the 46 points, because the five applied questions in that chapter are scored at two points each. Chapter 3 adds another 11 points. Between them, those two chapters are worth 27 points -- and the pass mark is 30. You cannot pass on chapters 2 and 3 alone, but you certainly cannot pass without them.
At the other end, chapter 4 is worth five points from five questions, every one of them at K2. That is roughly 11% of the paper for the most technical-sounding material in the module. Candidates who come from an automation background often spend the most time there because it is the part that feels like engineering, and it is the worst return on study hours in the syllabus.
The teaching-minutes column is ISTQB's guidance to accredited training providers rather than an exam weighting, and the two do not track each other neatly. Chapter 1 gets 100 minutes of instruction for 7 points; chapter 5 gets 80 minutes for the same 7 points. Across the five chapters the syllabus asks accredited courses for a minimum of 13.6 hours of instruction. If you are self-studying, that number is a useful sanity check on how long the material really is -- it is not a weekend.
What does Chapter 2 want you to be able to do with a prompt?
Compose one deliberately, apply a named technique to a named test task, and then judge the output against a metric instead of a feeling. Chapter 2 is where the applied questions live, so the phrasing of its objectives is worth taking literally: they ask you to write, apply and choose, not to recognise.
The syllabus describes a structured prompt for testing as having six components, and this is the single most examinable list in the module.
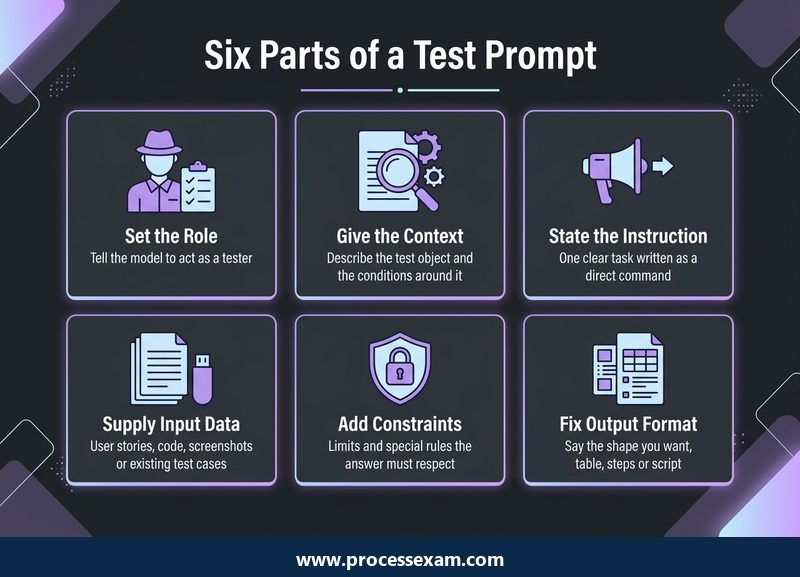
Each component does a specific job. The role sets the perspective the model should answer from -- tester, test manager, automation engineer -- and shapes its tone and assumptions. The context supplies the background needed to work out test conditions: what the test object is, which functionality is in scope. The instruction is the imperative task itself, kept clear and short. Input data is the raw material -- user stories, acceptance criteria, screenshots, code, existing test cases. Constraints say how the instruction should be applied to that data. The output format states the shape you want the answer in. The syllabus is explicit that this structure is meant to be combined with a prompting technique, not used instead of one.
The three techniques you will be asked to choose between
Prompt chaining breaks a task into a sequence of smaller prompts, where each result is checked and refined before it feeds the next. The syllabus places it where work is complicated enough to need decomposition and where intermediate outputs deserve inspection. Few-shot prompting puts examples in the prompt. Zero-shot gives none and leans on what the model already knows, one-shot gives a single worked example, few-shot gives several to pin down the behaviour you want. It earns its place where an example demonstrates the required output better than a description would. Meta prompting asks the model to draft or improve the prompt itself, in a loop the tester reviews -- useful when you are unsure how to phrase the request, and framed in the syllabus as a form of pairing with the tool.
Expect to be handed a testing situation and asked which of the three fits. The wrong answers in those questions are rarely nonsense; they are techniques that would work but fit worse. Practise justifying the choice out loud.
Judging what comes back
Section 2.3 turns evaluation into vocabulary you have to hold. Accuracy is overall correctness against expert-written test cases or requirements. Precision is correctness with respect to a specific objective, such as whether generated cases really do identify anomalies. Recall is the ability to find all the relevant instances -- whether generated cases cover the valid and invalid partitions of a data class. Relevance and contextual fit asks whether the output actually suits the test basis and the domain. Diversity asks whether the output ranges across user behaviours and edge cases or repeats itself. Execution success rate is the share of generated artefacts that simply run without syntax or format errors. Time efficiency is the saving against doing the work by hand. Several of these borrow testing vocabulary you already own, which makes them easy to half-learn and easy to miss on an understanding question.
How does the syllabus expect you to handle hallucinations, privacy and regulation?
By naming the failure, detecting it with a stated method, and mitigating it -- in that order. Chapter 3 is 11 points across 10 questions and covers four sub-areas, and it is the chapter that rewards structured revision most obviously, because its objectives are almost all recall and understanding.
Defects that belong to the model, not the code
The syllabus separates three things that are casually lumped together in conversation. A hallucination is output that is factually wrong or irrelevant to the task -- in testing, invented test cases, scripts that do not run, cases that verify acceptance criteria nobody wrote. A reasoning error is a misread of logical structure: cause and effect, conditional logic, step-by-step work. The syllabus points at test planning and test case prioritisation as the places this bites, and explains why -- models pattern-match rather than reason. A bias comes from the training data and tilts the output towards certain information or assumptions, which shows up in generated test data and in refined acceptance criteria.
Detection has its own named approaches. Hallucinations are caught by cross-verification against documentation and known behaviour, by consulting domain experts, and by consistency checks across outputs. Reasoning errors are caught by logical validation of the generated text and by output testing -- running the generated cases or scripts against the test object and looking at what happens. Bias is caught by reviewing whether the generated testware fairly represents the agreed strategy and coverage, and by watching for whole test types that quietly go missing from the output. Sitting behind all of it is non-determinism: the syllabus is clear that the same defect can look fixed in one conversation and return in the next.
Privacy, energy and the rulebook
The remaining three sub-areas are shorter but each carries a question or more. Data privacy and security covers the risks of putting real test data and product detail into a model, the vulnerabilities that come with generative tooling in the test process, and the mitigations. Energy consumption and environmental impact is a single understanding objective about how task characteristics and model choice drive energy use -- unusual on a testing paper, and precisely the kind of objective candidates skip. The last sub-area is a recall objective on AI regulations, standards and best-practice frameworks relevant to testing with generative AI. Recall means recall: know the names and what they govern.
What do the infrastructure and adoption chapters ask of a tester?
Explanation, not implementation. Chapters 4 and 5 are worth 12 points between them and contain no applied objectives at all, which tells you exactly how deep to go.
Chapter 4 asks you to explain the components of an LLM-powered test infrastructure and how it differs from a chatbot: a front end where testers put queries, a back end handling authentication and data, external data sources, and the model itself. Then two extensions -- retrieval-augmented generation, which grounds answers in your own documents, and LLM-powered agents that take on repetitive test work. The second half of the chapter is fine-tuning a model for particular test tasks, and LLMOps, the operational practice of deploying and managing models in a test environment. Five questions, all at understanding level. You need to be able to say what each thing is and why you would reach for it, and nothing beyond that.
Chapter 5 is the organisational one, and it is worth 7 points -- the same as chapter 1, despite being the shortest chapter in teaching minutes. Shadow AI leads it: the risk of staff using personal AI tools outside any policy, with the security, compliance and intellectual property exposure that follows. Then the ingredients of a generative AI strategy for testing, built on measurable objectives such as shorter test cycles or better test quality, matched to a model choice that fits the existing infrastructure. Then criteria for selecting between larger and smaller language models for a given task, including what they cost to run. Then the phases of adoption. The final section is change management: the skills testers need, how to build those skills in a team, and how test processes and responsibilities shift once the tools are in place.
Four of chapter 5's seven questions are pure recall. That is a genuinely cheap seven points for anyone willing to learn a handful of lists properly, and it is the section most often left unread because it sounds like management filler.
How should you split your study time, and what loses points?
Weight your hours the way the paper weights its points, and spend the difference on applied practice rather than re-reading. A four-week shape that matches the marking scheme looks like this.
- Week 1 -- ground yourself. Read chapter 1 and chapter 5 together. Both are 7 points, both lean on recall, and getting them out of the way early leaves the rest of the month for the expensive material. Write out the keyword lists at the head of each chapter and learn them as definitions.
- Week 2 -- live in chapter 2. This is the 16-point chapter. Take a real user story from work and write a six-component prompt for test analysis, then one for test design, then one for regression. Run them. Rewrite the weak ones. Do the same task with few-shot and with chaining and note which left you less rework.
- Week 3 -- break things on purpose. Work chapter 3 by producing the failures rather than reading about them. Prompt for test cases against a requirement you know well and hunt for the invented ones. Ask for a prioritised test plan and check the logic. Then learn the detection and mitigation lists cold, plus the regulation names.
- Week 4 -- chapter 4, then timing. Give chapter 4 two focused sessions and no more; it is five points. Spend the rest of the week on full-length timed runs, because a 60-minute paper with only eight spare minutes punishes hesitation more than ignorance.
Once the syllabus is genuinely read, the useful next step is answering questions under the clock until your pace is boring, and a full-length CT-GenAI mock exam is the most direct way to find out whether 40 questions in 60 minutes is comfortable for you yet. Before you pay for anything, work through ISTQB's own CT-GenAI Sample Exam A question paper -- it shows the house style of the wording better than any description of it can -- and the free sample questions for this module on our site.
The mistakes that cost points
- Revising an old download. A v1.0 copy will not mislead you on structure, but the wording of definitions has moved. Check the cover date.
- Studying tools instead of the syllabus. The exam asks about prompt structure, technique choice and evaluation metrics. It does not ask which product you use.
- Treating chapter 4 as the hard part. It is five points at understanding level. The hard part is the twenty-six understanding questions spread across everything else.
- Skipping energy consumption and regulation. Two objectives, both easy marks, both routinely ignored because they feel peripheral.
- Reading applied questions at recall speed. They get three minutes each in ISTQB's own timing model. Spend them.
- Assuming the pass mark is a question count. It is 30 points of 46. Dropping the six two-point questions costs you twelve points, not six.
CT-GenAI is a young module with a small paper and a published marking scheme, which makes it unusually easy to prepare for deliberately. Read the version in force, put your hours where the points are, and practise the applied chapter until writing a structured prompt is automatic. That is most of the work.
Frequently Asked Questions
What is in the ISTQB CT-GenAI syllabus?
Syllabus v1.1 has five examinable chapters: an introduction to generative AI for testing, prompt engineering for test tasks, managing the risks of generative AI, LLM-powered test infrastructure, and deploying generative AI in test organisations. ISTQB asks accredited courses for at least 13.6 hours of instruction across the five chapters.
What is the passing score for the CT-GenAI exam?
You need 30 of 46 points, which is 65%. The paper has 40 questions, but applied questions are worth two points each while recall and understanding questions are worth one, so the point total is higher than the question count. The pass mark is a point total, never a count of questions.
Do I need CTFL before taking the CT-GenAI exam?
Yes. ISTQB states on the certification page, and again in section 0.6 of the syllabus, that the Foundation Level certificate must be held before sitting CT-GenAI. It is an entry requirement rather than advice, so factor a Foundation Level attempt into your plan if you do not already hold it.
How much does the CT-GenAI exam cost?
The exam fee is USD $199 and the exam is delivered through Pearson VUE. Accredited training is optional for this module and priced separately by each provider, so a self-study route means the exam fee plus whatever practice material you decide to buy.
How long is the CT-GenAI exam and is there extra time?
The paper runs for 60 minutes. Where the exam is not delivered in your native language, ISTQB publishes an allowance of 25% more time, giving 75 minutes. Its own timing model budgets one minute for each recall or understanding question and three minutes for each applied question, totalling 52 minutes.
- Specialist |
- ISTQB Testing with Generative AI Test Questions |
- CT-GenAI Question Bank |
- CT-GenAI Body of Knowledge (BOK) |
- CT - Testing with Generative AI Simulator |
- CT - Testing with Generative AI Mock Exam |
- ISTQB Testing with Generative AI Book |
- ISTQB CT-GenAI BOK PDF |
- Testing with Generative AI Certification Cost |
- Testing with Generative AI Certification Requirements |
- ISTQB CT - Testing with Generative AI Question Bank |
- ISTQB CT - Testing with Generative AI Book |
- ISTQB CT - Testing with Generative AI Study Guide |
- CT - Testing with Generative AI Certification |
- CT - Testing with Generative AI Certification Cost |
- CT - Testing with Generative AI Certification Requirements |
- ISTQB Testing with Generative AI Sample Questions |
- CT-GenAI Exam Questions Download |
- CT-GenAI Test Questions |
- Testing with Generative AI PDF |
- ISTQB CT - Testing with Generative AI Exam Questions |
- ISTQB CT - Testing with Generative AI Sample Questions |
- CT - Testing with Generative AI |
- CT - Testing with Generative AI PDF


